Trigger Interfaces and PR Delivery Contracts Engineering Teams Should Demand From Async Agent Platforms
Vendors promise capability, but teams should demand commitments on triggers, PRs, and failures.
The best cloud coding agents for engineering teams are those whose trigger interfaces and PR delivery commitments match the team’s workflow. Vendor-managed execution removes the need to manage agent infrastructure, but not the need to govern its output. A sound platform choice rests on verifiable obligations for starting work, returning reviewable PRs, surfacing failure, and controlling repository access.
Why async coding agent platforms require a contractual mindset, not a capability one
Capability marketing says what an agent can do. An operational commitment sets out what happens after a team hands off work and leaves. A task can enter a queue but never start, or an agent can work without opening the expected PR. Neither failure is necessarily visible to the engineer who initiated the task. The absence of a person at the keyboard makes accountability more important.
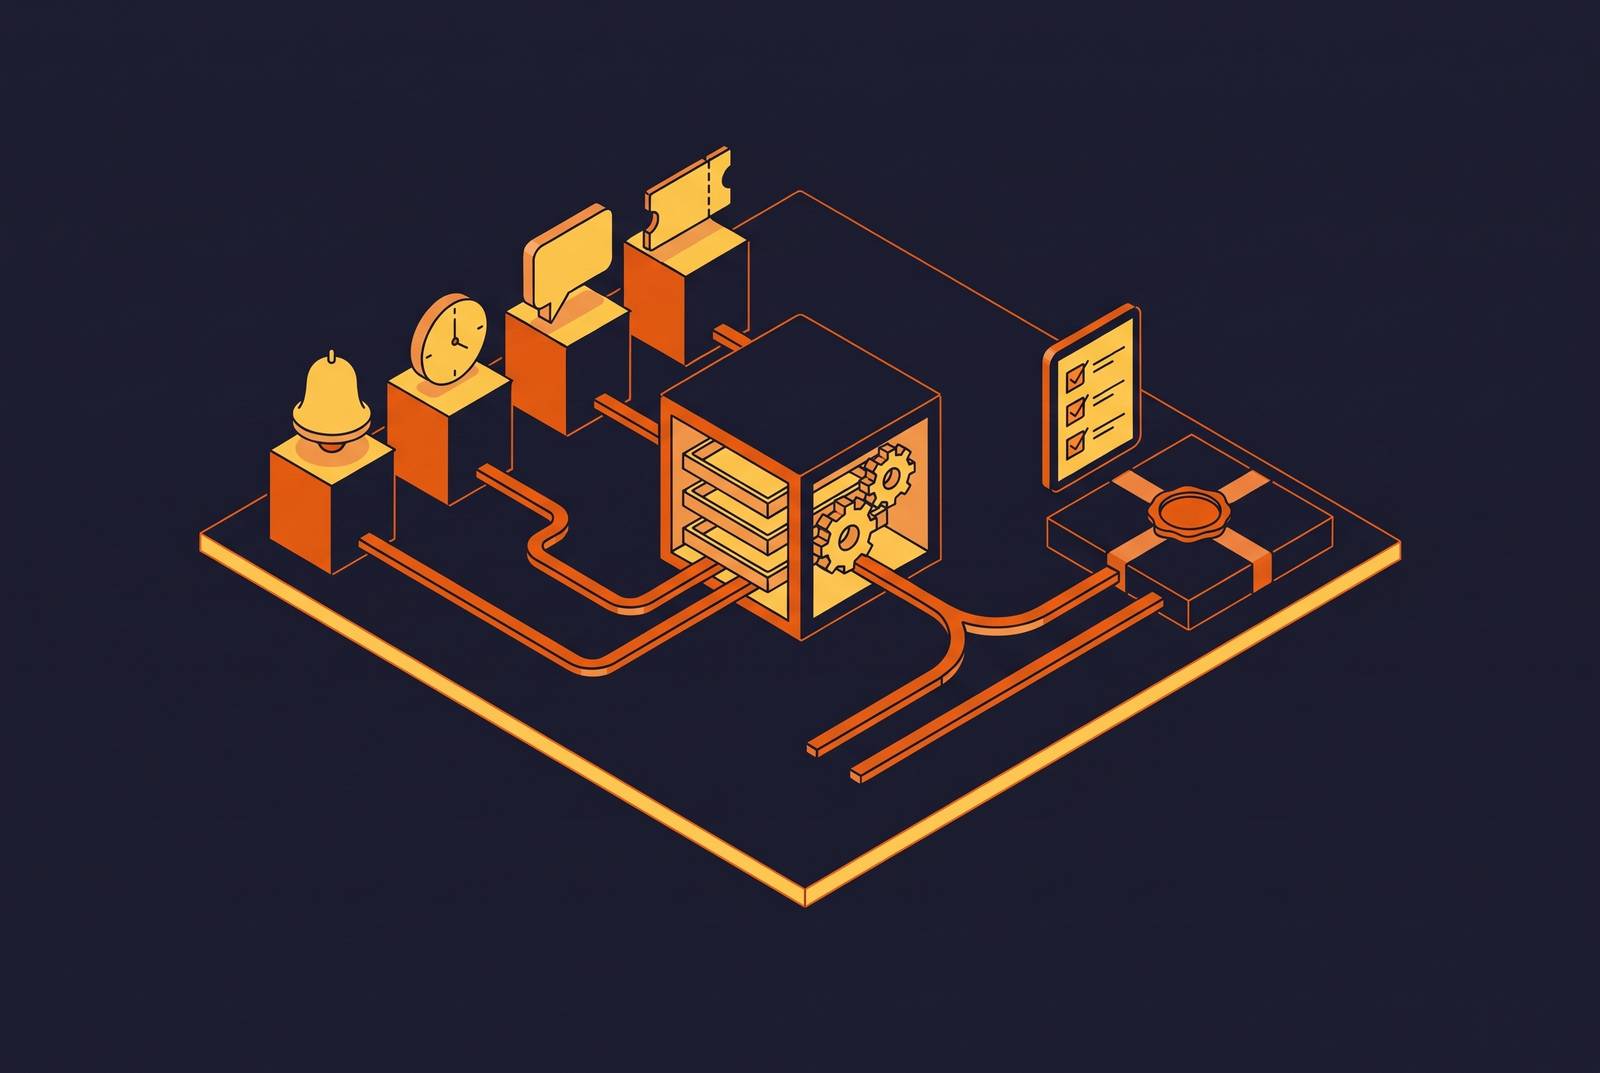
With event-driven execution, that responsibility goes beyond a single request. Agents can wake on pull request activity, Slack thread replies, schedules, and API calls, so execution no longer depends on someone watching a session. A missing trigger or an unreported failure can interrupt that workflow without an immediate signal. Engineering leaders should therefore ask what the platform can be held to.
What the trigger surface of a platform actually consists of
A platform’s trigger surface is the full set of entry points through which work can reach an agent without an open editor or an engineer actively at the keyboard. It begins with an invocation, such as an issue assignment, chat mention, web prompt, API call, or CLI handoff. Execution then moves outside the engineer’s machine. The agent clones the repository, installs dependencies, and works in an isolated VM or container managed by the vendor or the team’s own infrastructure. A branch, diff, or draft PR supplies the reviewable result that distinguishes this category from chat assistants.
Those entry points serve different operational needs. Scheduled triggers start recurring maintenance without someone having to start it by hand. Event-driven triggers pick work back up after PR activity, including a CI failure or review comment. API and webhook triggers connect pipelines, monitoring tools, and internal systems, while CLI handoffs let engineers delegate from a terminal.
Breadth is the first dimension to audit. A platform may take interactive requests but lack the scheduled or event-driven entry points that keep work moving after the first handoff.
Which cloud coding platforms support Slack, GitHub, and other triggers today?
Cursor Cloud Agents supports starting and managing work from the Cursor editor, a browser, a native iOS app, or an @cursor mention in Slack. With its August 19, 2026 update, Cursor added subscriptions that wake agents on pull request activity, Slack thread replies, and schedules. Repository support includes GitHub, GitLab Cloud or Self-Hosted, Bitbucket Cloud, and Azure DevOps. Teams that use other internal version-control systems may still run into limits.
OpenAI’s official Codex Cloud documentation describes task entry through the web or desktop app using “Work in > Cloud,” mobile access, the CLI, and GitHub @codex mentions. Linear Agent offers an issue-native route that looks into newly reported issues before they reach an engineer. Coinbase’s internal agent Forge is callable from Slack, GitHub, or Linear. Forge is built for use inside the company and is not a platform teams can buy.
Support for one chat or repository interface does not establish support for schedules, webhooks, or persistent event subscriptions. Nor does accepting a request establish what the platform will return. That requires a separate delivery commitment.
What PR delivery contracts actually mean and why platforms rarely make them explicit
A PR delivery contract is a set of verifiable commitments. It specifies the reviewable output, the evidence accompanying it, and the response when work cannot be completed. When the work succeeds, it should yield a draft PR with commit messages, an execution plan or session log, and test run artifacts. An opaque diff is not enough. A finished merge also bypasses the review boundary this contract is meant to preserve.
Execution evidence makes the result inspectable. Session logs and CI results show what happened, while Cursor also provides video recordings and screenshots that help reviewers validate changes without pulling the branch locally. When execution fails, the platform must notify the requester and preserve completed work. The obligation should also extend to picking up review comments and pushing revised commits to the same PR. Watching CI and acting on failures also saves someone from having to prompt the agent by hand.
The information asymmetry is structural. Vendors have a reason to show off successful PRs, but when work runs unattended, no one is there to see a task get dropped. Vendor-quoted merge rates diverge substantially from independent measurements across real-world tasks, so teams should treat headline rates as upper bounds. Explicit output and failure obligations make those missing outcomes part of the evaluation.
How event-driven agent subscriptions change the PR delivery obligation
A persistent goal changes the unit of delivery. When an agent sleeps between events and resumes after a review comment, CI failure, or Slack reply, the contract must cover the whole loop, including its first PR. The platform must keep track of the goal across those gaps. It must also let humans steer the work without terminating the session, a capability Cursor introduced with its August 2026 subscriptions update.
Persistence also requires traceability and limits. Event provenance must expose whether Slack, GitHub, an API call, or a schedule drove each step, so reviewers can reconstruct what prompted a commit. Automatic CI autofix must be controllable globally and per PR, including through a PR comment. Otherwise, a team cannot selectively stop automated intervention on a production path while retaining it elsewhere.
Coinbase’s Forge illustrates the complete delegation loop. A Slack bug report becomes a labelled, sized, and assigned Linear issue, followed by a drafted fix, a PR, and a return notification to Slack for review. No human has to re-enter the workflow between those stages. For that pattern to be dependable, Slack intake, Linear issue creation, GitHub PR creation, CI monitoring, and Slack notification must each be delivery obligations. Treating them as optional integrations leaves the overall outcome unaccountable.
Where the PR delivery contract intersects with integration depth across Slack, Linear, GitHub, GitLab, and Sentry
An integration can accept work without completing the handoff. A shallow Slack integration starts a session but provides no thread update when the PR opens or CI fails. A deeper integration creates a tracked issue, returns the PR link, monitors CI, and posts when the agent pushes a fix.
Linear’s June 11, 2026 changelog describes an agent that follows team guidance, gathers evidence from Sentry or Datadog through MCP, and inspects the codebase before producing a fix. Linear uses this workflow internally to resolve roughly a third of incoming bug reports, mostly on the first pass.
OpenAI’s Codex bug triage pattern identifies a broader input footprint, including Sentry alerts, Linear and GitHub issues, PR checks, deploy logs, support tickets, and Slack threads. An alert-to-agent workflow depends on a first-class webhook or API trigger the monitoring tool can call directly. Repository coverage is equally decisive. Several platforms require GitHub-hosted repositories, so teams must check native support for their GitLab and self-hosted VCS needs before they commit, to avoid finding out during deployment that those systems are excluded.
What parallel agent execution demands from a PR delivery contract
Concurrent agents that produce colliding branches or duplicate PRs can create review debt faster than they clear engineering debt. Each session thus needs its own isolated VM, and the platform must coordinate branch naming and PR creation across sessions. Teams also need one interface for monitoring all running work. Queue, running, and failure states must be visible so work can be prioritized or cancelled without losing state.
Philips Digital Computational Pathology illustrates structured parallel execution with Devin. Devin’s Code Scans use an agentic MapReduce pattern that divides a large codebase investigation into focused batches, distributes them across agents, and synthesises the results into one report. Philips reported a high PR merge rate and hundreds of engineering hours saved while testing was under way. The example shows why distributing work and consolidating its results belong in the same operational design.
Coinbase illustrates the opposite pressure on delivery infrastructure. One session produced hundreds of PRs in minutes, and across sessions its agents have taken GitHub down four or five times. Output volume alone is not success. At that scale, platforms need enforced rate limits and teams need enforced review capacity, or faster execution simply moves the bottleneck into the systems and people receiving the work.
The security and governance obligations that belong inside a PR delivery contract for regulated teams
An agent opening PRs against a production repository is a non-human identity with write access to code. Before granting that access, regulated teams should demand written commitments defining what the identity can touch, what it records, and how access can be revoked. Session isolation is an entry-level requirement. Each session must run in an isolated VM to keep credentials, file-system state, and network access from leaking between sessions. Git credentials should remain outside the sandbox, with a proxy authenticating on the session’s behalf.
Auditability must outlast execution. Records for each session should show which files it touched, which commands it ran, and what triggered each action, even after the session ends. Role-based access controls must set limits on access by repository, branch, and environment. SSO/SAML and SCIM should connect agent access to the existing directory. Teams with data residency or restrictive cloud policies also need a path to execute within their own infrastructure.
Deployment labels require careful interpretation. Cognition’s documentation places customer-managed encryption keys in Devin’s Enterprise Assured deployment as a tier-specific control among VPC deployment tiers. Written commitments should distinguish such tier-specific controls from general hosting claims.
The security audit should also address three failure patterns. Developer credentials can pass into an agent shell and reach production, while secrets committed for local convenience become readable to sessions with workspace access. When infrastructure can be reached only through CI, an agent that cannot reach it may invent shortcuts that bypass review. These are delivery risks because they affect both how a proposed change was produced and where it ran.
The concrete checklist engineering leaders should apply before committing to a platform
Can the team initiate work through its actual mix of Slack, issue assignments, schedules, PR events, APIs, webhooks, and terminal handoffs? Does the platform support the team’s repository host, including GitLab or self-hosted VCS where required? A missing route is a workflow constraint. It should be identified before a pilot is treated as evidence of production fit.
Does every session that finishes return a reviewable PR with commit messages, session logs, and test artifacts, and does work left unfinished produce a failure signal the team can see? Can review comments and failed CI checks drive revisions to the same PR? Are autofix controls and event provenance available at the required scope?
Scale and access require separate acceptance checks. Can concurrent sessions run in isolated VMs without branch collisions, with one view of queue and execution state? Are credentials proxied, audit records retained, and repository, branch, and environment permissions governed through RBAC? Does identity management support SSO/SAML and SCIM, and is self-hosted execution available where policy requires it? Written answers establish the boundary of delegated authority.
Commercial terms complete the evaluation. Can the platform use the team’s own model accounts and keys so model costs stay with the subscriptions the team already has? Is compute charged by workspace minute, with no charge while sessions are idle? A platform commitment should make unattended execution accountable across workflow, review, access, and cost, rather than leave those obligations for the engineering team to discover after delegation.